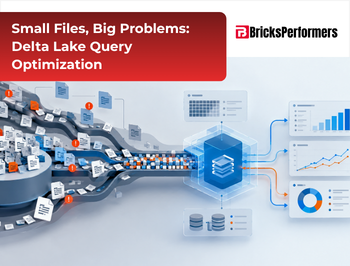
In modern data platforms, Delta Lake is used extensively to manage and process huge amounts of structured and unstructured data. In Databricks, Delta Lake provides robust data management, scalable analytics, and efficient data processing capabilities. Despite being a highly optimized Delta Lake table, however, performance issues may arise if there are too many small data files stored within the table.
In Delta Lake, this is referred to as the small-file problem. The issue arises when data comes into Delta Lake on a regular basis in small increments (i.e., frequent batch arrivals), there are many write operations made to Delta Lake by streaming pipelines, or data transformations lead to the creation of many output files. As the number of files increases, Spark will use more of its time finding files, reading file metadata, assigning tasks, and dealing with overhead than it will spend working with actual data.
As a result, you may experience slower SQL queries, inefficient ETL pipelines, longer-running MERGE operations, and increased compute costs.
Businesses can use Delta Lake file compaction, optimized writing, automated compaction, correct data organization, and ongoing performance tracking to overcome the problems associated with this issue.
This article provides an explanation of why small file sizes impact Delta Lake’s query performance and offers solutions to improve performance by utilizing real-world optimization strategies within Databricks.
What Is the Small-File Problem in Delta Lake?
Delta Lake writes all table data to parquet format and tracks the changes to each table via a transaction log so it can ensure that table data remains consistent. If an application is writing small volumes of data into the same table on an ongoing basis, the table will end up having thousands, or potentially millions, of very small files.
To illustrate this point, consider a customer transaction analytics platform which processes data every couple of minutes. As part of each transaction processing cycle, the platform writes a small number of records to a Delta Lake table. At the end of a few weeks, the table could potentially have a very high file count, despite having a relatively small overall dataset.
The process of reading that table using Spark will require it to locate the correct files, create a plan for the task at hand, create a schedule for the processing of those files, and then process the data. There is potential for significant overhead when managing thousands of small files.
Smaller numbers of properly sized files may provide for greater efficiency in scanning data; however, what constitutes an “ideal” file size depends upon many factors, including but not limited to workload, table layout, and available computing power.
Small files are not inherently evil. They offer benefits such as being able to process data incrementally and ingest data at a fast rate. However, when you have a lot of small files accumulated, and you don’t have a plan in place to clean up after them, then you will experience issues.
Why Small Files Reduce Delta Lake Query Performance
1. Increased File Listing and Metadata Overhead
Before Spark can begin processing data, it must determine which files contain data relevant to the query being executed. Delta Lake relies on both transaction logs and file statistics to track table states and identify data that may need to be accessed.
If there are too many small files in a table, it may cost more to find those files and process their metadata.
In another instance, when a user is querying only a minor part of a transaction table, but the table contains a large amount of unnecessary files for evaluation, then there can be substantial planning required.
The additional cost is most apparent when executing queries with few results, but they require a great deal of time before they can begin to process.
How to resolve this issue: As a component of routine Delta Lake Table maintenance, reduce the file counts of small files and track file counts. Reducing the number of extra files created will allow users to focus their query efforts on the actual data rather than managing files.
2. Excessive Spark Task Scheduling
Apache Spark is designed to process data using tasks that run on the computer systems (or “nodes”) that are currently being used to perform the processing. If your data is split into numerous very small files, then Apache Spark will typically create a high number of scan tasks to read all those files.
Excessive numbers of tasks using parallel processing will result in higher levels of scheduling overhead and decrease efficiency during the execution process.
In contrast, a query that involves reading thousands of very small files will result in a large number of short-duration tasks. The time needed to manage and coordinate all those tasks will be quite substantial in relation to the quantity of information each task handles.
How to resolve this issue: Use file compaction to combine many smaller files into fewer large files. File compaction can decrease the number of scans needed to process data, as well as increase the overall processing speed if the compact files are compatible with your application’s workload and available parallelization.
3. Slower Analytical Queries
Many times, when business intelligence dashboards or analysis questions are being used, you will find yourself filtering, aggregating, and/or joining data from your Delta Lake tables.
The query performance will decrease if the tables contain an excessive number of smaller files. This results in greater scanning overhead. This can result in slower report delivery time and reduced responsiveness for your data-driven application.
Small files are not the sole reason for slow query performance. Other potential causes include: poor organization of your data; poor performance when joining tables; large variations in the number of records contained within each table (data skew); many expensive transformations performed on each record; and insufficient computing capacity to support your queries.
How to resolve this issue: Prior to making any modifications to the query execution plan or the performance metrics, review both. If you see that there is too much file overhead, then consider compacting the table and evaluating if either better data skipping or improved clustering will make the query pattern work more efficiently.
4. Higher Compute Costs
When there is a large amount of overhead associated with managing files, organizations will find that they require more processing time to finish their current tasks. This is because slow queries can take up compute resources for an extended period of time.
This may result in increased costs for your scheduled ETL jobs, your SQL workloads, and your downstream analytics.
The addition of compute resources will potentially improve certain tasks; however, it does not guarantee that file layout issues have been fixed. At times, the base issue remains after expanding resource allocation.
How to resolve this issue: Determine if file overhead is a problem area. If so, optimize the layout of your tables. Measure the difference between before and after optimizing the tables, in terms of execution time, compute usage, and data scanned, to assess if the optimization was worthwhile.
How to Improve Delta Lake Query Performance
1. Use OPTIMIZE to Compact Small Files
The most effective way to solve the issue of small files is to use Delta Lake’s OPTIMIZE command.
OPTIMIZE in Databricks rewrites data files so that the data file structure will be more efficient. When optimizing standard Delta Lake tables that have no liquid clustering applied to them, OPTIMIZE will combine small files into fewer large files. If the Delta Lake table being optimized uses liquid clustering, OPTIMIZE will also reorganize the data within each file based on the clustering keys.
For example, the following SQL statement optimizes a Delta Lake table:
OPTIMIZE sales_transactions;
When a table has been partitioned, and you need to perform maintenance on only a specific date range, you may target the appropriate partition range.
OPTIMIZE sales_transactions
WHERE transaction_date >= ‘2026-10-01’;
Use predicates appropriate to the table’s actual partitioning and schema.
Compacting files will allow you to read from your tables faster and without affecting how the data is stored logically in those tables. Delta Lake’s transaction log provides a consistent view of the table while the physical layout of the table is updated.
When working with large tables, do not indiscriminately optimize all of the data within the table regularly. Establish a maintenance program that is based upon how often new data is added to the table, how well the queries performed against the table are running, and how many new files have been created since the last time the table was maintained.
Please refer to the Official Databricks Guide on Optimizing Data File Layout for all of the different options and behaviors that are available to you.
2. Enable Optimized Writes
The purpose of compaction is to correct the way that files are laid out on your computer after they have been created. On the other hand, the goal of optimizing how you write files is to prevent the creation of many small files.
This option improves the way data is written to output files. It is especially beneficial for workloads that write to partitioned tables, which would have had numerous small output files accumulating in different partitions without this option.
An example of this would be when an ingestion pipeline that handles frequent transaction batches creates many small files when each batch is written to disk separately. To create a more appropriate file structure for your needs, you can use optimized writes while writing the data to disk.
In Databricks, depending on the table being used, the runtime being executed on, and the way that the Databricks environment is configured, the automatic enablement of optimized writes may have occurred or be managed for you. Before making any manual adjustments to your write configuration or enabling legacy settings in your code, first determine what the current state of optimization for writing data into your Databricks tables looks like.
The best approach is to assess the value of using optimized write techniques with frequently generated small file workloads. However, be sure to weigh the benefits against the drawbacks. When data is shuffled during writes, there may be an increase in write latency, although this can lead to improved read performance later.
3. Use Automatic Compaction
After writing, automatic compaction takes action against small-file accumulation through the process of combining eligible files.
This is also beneficial for the automated ingestion pipeline, which generates many small files during the day. Rather than waiting until there is an obvious drop in performance of the query, automated compaction maintains a more effective file structure.
However, automated compaction will never replace the necessity of periodic optimization. This is due to its behavior depending on the environment, configuration, and the workload of tables.
With predictive optimization turned on in Unity Catalog-managed tables, Databricks can perform maintenance tasks like OPTIMIZE automatically. This will likely lessen the frequency of having to schedule maintenance tasks manually.
Prior to executing a new compaction procedure on your table, verify if there is an existing automated maintenance feature for the table.
To avoid unneeded maintenance work and also avoid an accumulation of small files at a rate that cannot be handled.
4. Avoid Over-Partitioning Delta Lake Tables
Partitioning creates logical groupings of a table’s data based on user-defined criteria (i.e., specific column values). When users frequently filter data in their queries using columns that define how the data was partitioned, partitioning can enhance the speed at which those queries run.
However, when you use a column that has a high number of unique values for partitioning (high cardinality), this will produce a great deal of very small partitions. When you have a partition that is populated with only a small amount of data, the system produces a large number of very small files.
Partitioning a transaction table by a unique customer ID would result in many partitions that contain very small amounts of data. The creation of such partitions can create an excessive amount of file management overhead.
Review the current partition columns to determine if they accurately reflect how you run queries against your data and how large your datasets are. Create partitions based upon columns that create relatively few, larger groups of data rather than many small groups.
Generally, Databricks recommends that users think about using liquid clustering as opposed to the traditional method of partitioning for all new tables created. Liquid clustering may be a better option than traditional partitioning if the user is struggling with managing the partitions statically because of either the way they are querying the data or how the data is being distributed.
The best way to handle tables will vary depending on how big the table is, how often it is accessed, and what type of computer you are using.
5. Use Liquid Clustering for Better Data Layout
File compaction can be used to decrease the number of files. However, it may not produce the most optimal arrangement of data for all types of queries.
Clustering in liquid form will help group similar types of data together by using the specified clustering criteria. It will also help the query engine skip the reading of files that do not seem to have the information needed for a match, thus improving the efficiency of the search process.
An analytics team may need to run queries on transaction data with customer IDs and transaction dates. By creating a clustering strategy that groups related records together, it will be easier to perform efficient searches using the columns.
Liquid clustering works particularly well when a table has frequent changes in how it is accessed, contains many unique values for the column used to filter, or when the way data is distributed makes traditional partitioning impractical.
It’s not a general-purpose solution to all your layout strategy problems. Base your choice of clustering key on how you typically access the data and then use that to evaluate if the results are what you expected.
6. Optimize Frequent MERGE Operations
Delta Lake MERGE operations are typically utilized for inserting new records into a table and updating currently stored records. When there are numerous MERGE operations (updates), this may cause the data files to become fragmented. This fragmentation can occur if ingestion processes handle very small batches of data.
For example, a pipeline used to analyze customers’ behavior updates a Delta table every few minutes. When there are many files touched during each update, and each update creates small output files, then as time passes, the table’s layout will become less efficient.
How to fix it:
- Review how often the pipeline runs, and see if you can combine several smaller batches without exceeding your latency requirements.
- By reducing the size of the search area for MERGE operations with valid constraints on what data can be processed, you will have a more efficient way to process your data.
- Review the writing of settings and how execution plans are set up to see if you have unnecessary shuffling or creating too many files.
- Apply appropriate compaction or automatic maintenance where needed.
Do not assume that all slow MERGE are due to small files. There are many other factors (such as the number of joins being performed, the amount of data being processed, how evenly distributed the data is across the partitions, and whether other processes are using resources) that can contribute to slow performance.
7. Monitor File Sizes and Query Performance
Effective Delta Lake optimization requires ongoing monitoring.
Track file count, file size distribution, query response time, data scanning rate, task count, and write pattern. These measures can be used to determine if the table has a small file issue and if your current optimization approach is effective.
Databricks query performance metrics help identify problems such as too many small file reads. Additional data about tables and how they run will provide more information.
Use a repeatable testing process:
- Record baseline query performance.
- Inspect file sizes and the query execution plan.
- Apply the relevant optimization.
- Run comparable queries under similar conditions.
- Compare runtime, data scanned, and compute consumption.
This technique can help differentiate between actual performance enhancements and those due to differences in cache usage, workload variations, or changes in compute environments.
Practical Example: Fixing Small Files in a Transaction Table
An online retailer has a transaction database that uses Delta Lake. The retailer’s data ingestion process is designed to write to the Delta Lake on a continuous basis (every five minutes), allowing for near real-time reporting.
Over many months, the database will accumulate thousands of very small files. As a result, daily revenue reports will begin to take longer, and the Data Engineering Team will need to add additional computing power to ensure that all reports are delivered on schedule.
File overhead was found to be a major cause of the delay, according to the findings from an investigation.
The team takes several steps:
- Reviews the ingestion pipeline to understand why it generates so many files.
- Enables or verifies optimized writes where appropriate.
- Uses OPTIMIZE to compact existing small files.
- Reviews partitioning and considers liquid clustering based on query patterns.
- Establishes monitoring to identify recurring file fragmentation.
After the changes are made, the team will compare the query performance and resource usage with the previous baseline.
The amount of improvement you see will depend on the size of your data set, how you have designed your workload, and what issues you had with the original design. This example illustrates an essential concept: before you assume that you need more computing power, fix the way your data is organized.
Common Mistakes to Avoid
These are some typical pitfalls to avoid while tuning the performance of Delta Lake queries:
If OPTIMIZE is run too often: Unnecessary rewrites use resources. Schedule Maintenance Based on Real File Accumulation and Query Requirements.
Arbitrary file sizes: the optimum size varies depending on the task and setup. Adhere to the current Databricks guidelines and validate results.
Over-partitioning tables: Excessive partitions are a solution that may lead to more small files.
Write patterns are ignored: If the files are continually written, then some of them might be too small for occasional compaction to be effective.
All the slow queries have the same reason: Data skew, expensive joins, poor filtering, and insufficient resources all lead to the same symptoms.
Running redundant maintenance jobs: Determine if the table requires redundant maintenance jobs, and if so, find out whether predictive optimization or other automatic maintenance capabilities are already performing it on your table.
Measuring ensures that organizations don’t incur unnecessary compute costs and that queries can be performed reliably.
Conclusion
Small files can cause serious performance issues in Delta Lake because of the excessive amount of management overhead they generate. They will require more time to locate files; they will require more Spark tasks; they will result in slower analytical queries; and they will lead to increased usage of computing resources.
To effectively address the issues of creating and accumulating small files, you will need to apply several techniques, including OPTIMIZE, optimized writes, automated compaction, appropriate data organization, and careful management of frequently applied MERGE operations. These techniques can significantly enhance the query performance of Delta Lake.
Instead of automatically using optimizing parameters, business owners should use performance indicators for query execution and table status.
Ultimately, improving Delta Lake performance is not just about having fewer files; it is about organizing your data so that you can support your workload and reduce the amount of unnecessary work required to process the data while providing consistent performance over time as you grow.
By implementing a consistent maintenance strategy and using evidence-based tuning, organizations will be able to develop higher-efficiency Databricks pipelines and manage the cost of large-scale data processing.
Frequently Asked Questions
- What causes small files in Delta Lake?
Small files are often the result of frequently writing small batches (micro-batching), repeatedly writing to the same location (repeated incremental writes), dividing data into too many partitions (over-partitioning), and transforming the data in such a way as to generate numerous output files.
- How does OPTIMIZE improve Delta Lake performance?
The OPTIMIZE command reduces file management overhead and increases read performance by rewriting data files to enhance table layout and compress smaller files.
- What is the ideal file size for Delta Lake?
In general, there is not a single optimal size for all types of workloads. The appropriate size of a file depends upon the amount of data, how the data will be queried, the amount of computing power available, and the Databricks environment. You should use the most recent Databricks platform guidelines as well as evaluate the performance of your own application.
- What is the difference between optimized writes and auto compaction?
Optimized writers attempt to create files that are closer to the ideal size when writing. Auto compaction combines files of a certain size (small enough) after a write operation completes. While both of these methods may alleviate the issues associated with too many small files, the methods and availability of each will vary based upon the environment.
- Can small files increase Databricks costs?
Yes, too much file overhead will result in increased execution times for your queries as well as more consumption of resources. While the amount of money spent is directly related to how many times you run those queries, smaller files are only one of several factors that can create expensive queries.
- How often should Delta Lake tables be optimized?
The amount of time between each automated maintenance task should be based upon the rate at which files are created, the number of times a query is made against the table, and whether automatic maintenance has been enabled. Perform performance monitoring and apply predictive optimization when necessary to prevent excessive manual maintenance.